Languages
Python · SQL · Bash · Java · C++
Cloud Data Engineer · Chennai, India
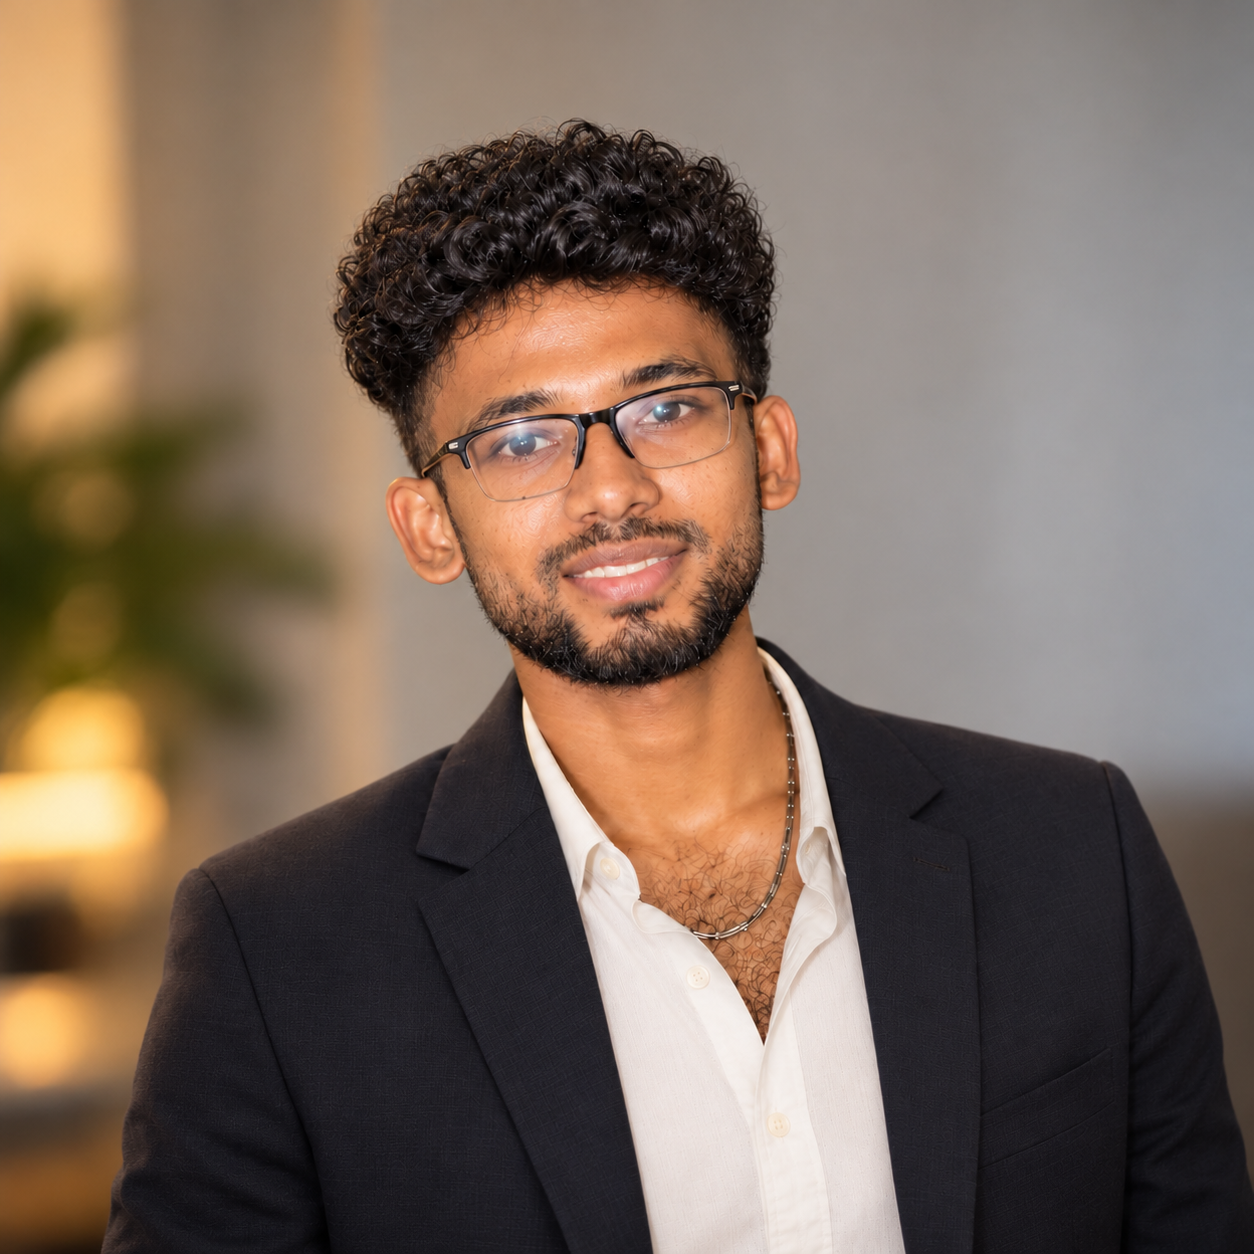
I'm a Cloud Data Engineer at TCS with 2+ years of experience building Python and AWS data workflows, and I build data-platform projects on the side with Kafka, Spark and Databricks. Open to Data Engineer, Cloud Data Engineer and AWS roles.
About
I turn messy, distributed data workflows into systems teams can depend on.
At TCS my work covers Python-based ingestion, SharePoint-to-S3 workflows, AWS data services, partitioning, job scheduling, production troubleshooting and documentation. I like finding the root cause of a failure also making the workflow easier to operate.
I explored streaming, lakehouse patterns, data quality and orchestration.
Skills
Python · SQL · Bash · Java · C++
S3 · Glue · Athena · Lambda · Step Functions · IAM · CloudWatch
ETL/ELT · ingestion · data quality · incremental processing · partitioning · pipeline troubleshooting
PySpark · Spark · Kafka · Airflow · Databricks · Delta Lake · dbt
Git · GitHub · Docker · CI/CD · PostgreSQL · MongoDB
Scikit-learn · PyTorch · TensorFlow · NLP · Computer Vision
Used professionally at TCS: Python, SQL, AWS (S3 and related services), ETL, Autosys. Spark, Kafka, Databricks, Delta Lake, dbt and Airflow are from projects and self-study. Depth varies by tool.
Projects
Flagship · Observability
Problem: pipeline incidents are slow to diagnose and risky to fix by hand.
What it does: detects pipeline failures, schema drift, late-arriving data and volume anomalies, then produces an evidence-based diagnosis and runs safe, audited retries.
Design decisions: replayable event landing, and a retry path restricted to an allowlist with an audit trail.
View on GitHub ↗Streaming · Lakehouse
Kafka ingestion, Spark transformations, Databricks lakehouse storage and dbt modeling on NYC Taxi data.
Find on GitHub ↗Healthcare · NLP
Healthcare data management and patient–doctor interaction system with NLP symptom extraction and decentralized record storage. Academic project, not a clinically validated system.
Find on GitHub ↗Earlier projects: Voice-Controlled Object-Finding Robot · Vehicle Damage Estimation · The Language of YouTube
Experience & Education
Jul 2024 — Present
Project work above is separate and not part of my TCS role.
Education
VIT Chennai
Certification · July 2025
CLF-C02
Earlier experience
Applied ML, Python, model evaluation, Flask.
Resume
Contact
Open to Data Engineer, Cloud Data Engineer, AWS and Data Platform roles.